Skip to content

the tiny-hardware AI vertical

EDGE.

AI on the smallest machines.

The latest in LLMs on microcontrollers, tiny language models, and hands-on build logs — what actually runs on an ESP32-class board, measured in real tokens per second, delivered newsletter-style.

  • 28.9M paramson an $8 ESP32-S3
  • ~9.9 tok/sfully on-device
  • 450 B flashread per token
  • 180.9M MoEon ESP32-P4

The authored work: deep dives, scoops, and honest analysis of who built what — with the builders credited by name.

Flipper One Wants to Be the First Hacker Tool With a Local LLM — What Its 6 TOPS NPU Can Actually Run
Edge AI7 min read

Flipper One Wants to Be the First Hacker Tool With a Local LLM — What Its 6 TOPS NPU Can Actually Run

Flipper Devices' pocket Linux box promises an LLM that runs offline and knows the device inside out. Rockchip's own numbers say what a 6 TOPS RK3576 really does — and the NPU driver isn't in the kernel Flipper chose.

258 views
Read
AMD Just Bought the 'Ollama of NPUs': What FastFlowLM Means for Local LLMs
Edge AI6 min read

AMD Just Bought the 'Ollama of NPUs': What FastFlowLM Means for Local LLMs

A 17MB runtime that runs LLMs on AMD's Ryzen AI NPUs — built by three academics, acquired by AMD on July 17, 2026, folded into ROCm in August. The NPU rung of the edge ladder just got real.

417 views
Read
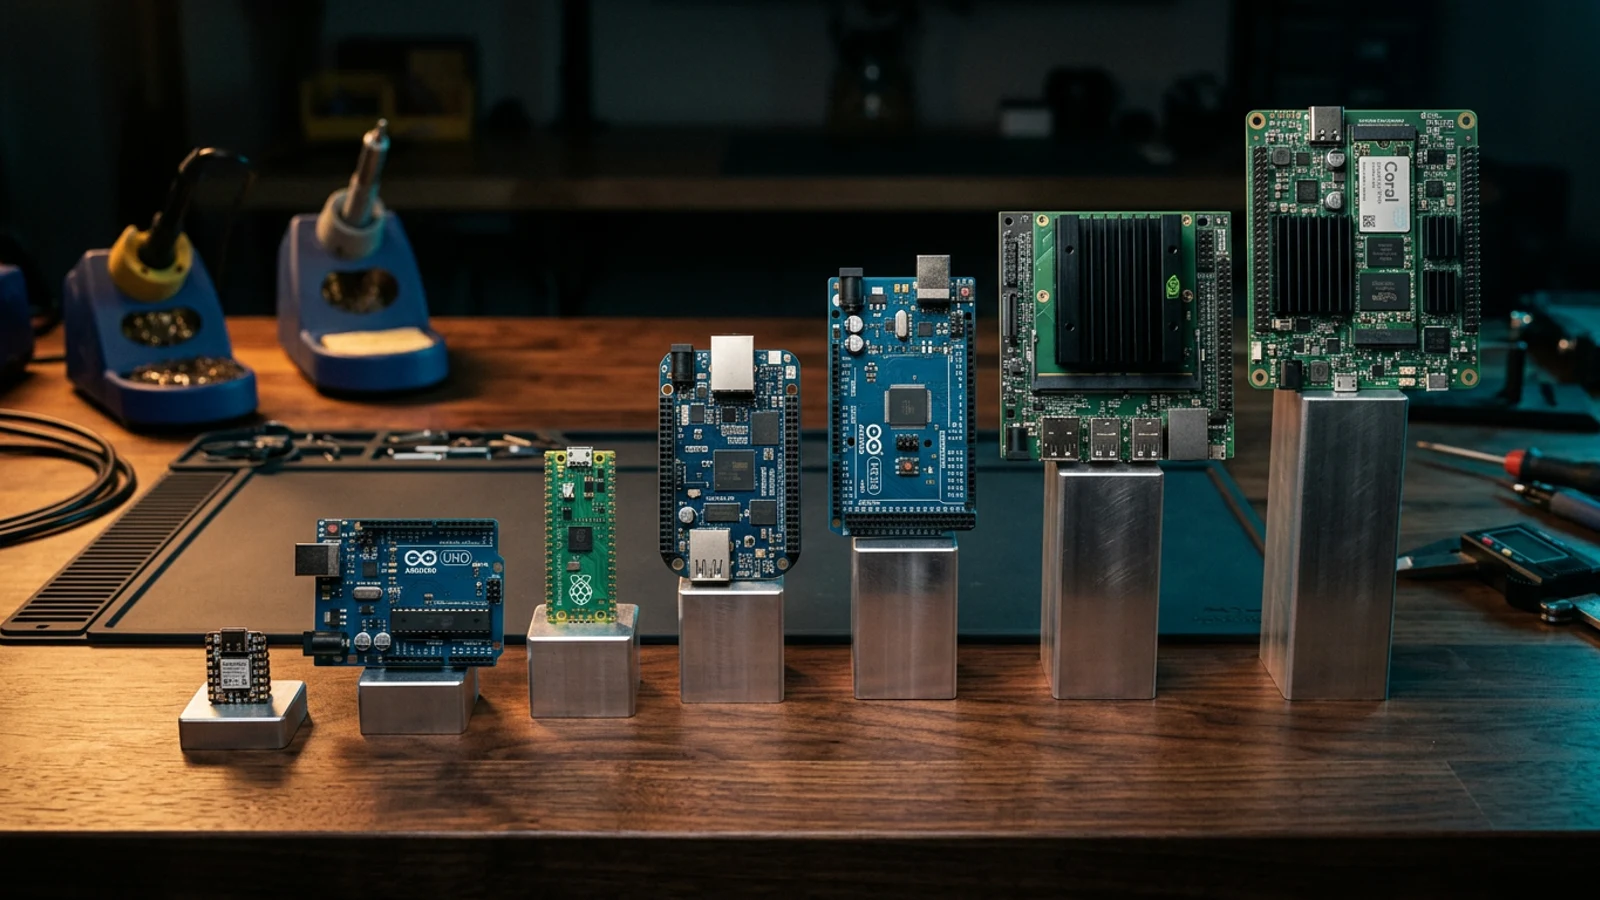
The Edge AI Compute Ladder: What Actually Runs on Every Board From $5 to $600
Edge AI8 min read

The Edge AI Compute Ladder: What Actually Runs on Every Board From $5 to $600

A $5 Pico 2 writes TinyStories. A $15 Pi Zero 2 W runs SmolLM2-135M. A $299 RISC-V board claims 30B. What AI really fits at every rung of the edge hardware ladder.

375 views
Read
The 180M-Parameter LLM Running on a $10 Microcontroller — and Almost Nobody Noticed
Edge AI7 min read

The 180M-Parameter LLM Running on a $10 Microcontroller — and Almost Nobody Noticed

On August 5, 2026 a 180.9M-parameter mixture-of-experts LLM ran on a $6-10 ESP32-P4 — and got two Hacker News points. The undercovered microcontroller AI story of the year.

197 views
Read
Running an LLM on an $8 Microcontroller: What's Real in 2026
Edge AI9 min read

Running an LLM on an $8 Microcontroller: What's Real in 2026

In July 2026 a 28.9-million-parameter LLM ran fully on-device on an $8 ESP32-S3 at almost 10 tokens per second. Here's how the trick works, who built it, what's hype, and what you can actually build with a microcontroller LLM today.

339 views
Read

The daily dispatch

All dispatches →

An AI-researched briefing on the last 48 hours of edge AI, published every morning — every item verified, every source credited. Our way of dispatching.

  1. 27 viewsESP32 Special: Two Offline Voice-AI Builds Debut While a New Chip Powers a Display BoardTwo fresh ESP32 voice-AI repos go fully offline, a mystery ESP32-S31 chip shows up on a display board, and an ESP32 radio hack learns to transmit.
  2. 50 viewsA 35B MoE Vision AI Learns to Fit a Phone While a $7 ESP32 Hijacks an iPhoneOpenBMB squeezes a 35B MoE vision model onto an iPhone, Google shrinks multimodal search to 191MB, and a $7 ESP32 learns to tap a real iPhone's screen.
  3. 96 viewsA Hexagon NPU Learns New AI Tricks While Edge Robots Get Lighter World Modelsllama.cpp opens a path to Qualcomm's Hexagon NPU, a 2-bit automation model surges on GitHub, and a lighter world model targets robot arms.
  4. 76 viewsA 1-Bit AI Trick Shrinks a 70B Model to Fit on a $200 GPUSamsung's sub-1-bit quantization paper gets a reality check, plus fresh research on tiny LLMs and ESP32 voice silicon.
  5. 78 viewsSmall AI Models Steer Robots While ESP32 Boards Do the Grunt WorkA dual-core Arduino runs robot policies on-device, a paper argues for skill-sized models over one big brain, and two ESP32 boards ship.
  6. 131 viewsWindows Learns GGUF as AI Agents Design Their Own Inference ChipMicrosoft wires llama.cpp into Windows ML's NPU stack while an agent-built FPGA accelerator and fresh AI PC benchmarks show where edge inference actually stands.
  7. 98 viewsA 14M-Parameter LLM Keeps a Virtual Fish Tank Alive on an $8 ChipA distilled LLM runs a fish tank on an $8 ESP32-S3, four Raspberry Pi 5s share a 30B model, and a 2B decision model lands for edge agents.

Bench logs

First-person experiments on real hardware — flash it, run it, report the tokens per second.

LOG 001 · SOLDERING
The first bench log is being soldered together — hardware is on order.
VIDEO · SOON
Video bench logs — coming to YouTube. Real boards, real tokens/sec.

The state of the art, honestly

“LLM on an ESP32” means four very different things. Here's the taxonomy, ordered from genuinely on-device to a cloud demo wearing a microphone.

True on-device

esp32-ai

A 28.9M-param TinyStories model running fully on an $8 ESP32-S3 at ~9.9 tok/s. Writes little stories; can't answer questions.

Streamed weights

p-for-llm

A 180.9M MoE on ESP32-P4 at ~9 tok/s — compute is on-device, but the weights load over USB at startup.

Distributed MCUs

esp32s3-distributed-ai

56M params sharded across 3 ESP32-S3 boards talking over ESP-NOW radio — a tiny cluster, no router in between.

Cloud in disguise

most “ChatGPT on ESP32” demos

The board is a microphone; the model is in the cloud. Includes Espressif's official LLM solution. Not on-device at all.

Credits & sources

Edge reports on other people's soldering and science. Credit where it's due.

The hall of fame

feed

Individual developers doing the work that moves this field. The list only grows. Hover to pause, click through.

  • Andrej Karpathy — llama2.c2026-08The single-file C inference engine nearly every MCU port builds on.
  • Georgi Gerganov — llama.cpp / ggml2026-08The quantized-inference stack that made on-device LLMs a movement.
  • slvDev — esp32-ai2026-0828.9M-param LLM on an $8 ESP32-S3 via Gemma-3n-style per-layer embeddings. MIT.
  • cyfrit — p-for-llm2026-08180.9M-param ternary MoE on ESP32-P4 with early tool-calling.
  • wladimiravila — esp32s3-distributed-ai2026-0856M params across 3 boards over ESP-NOW.
  • DaveBben — esp32-llm2026-08The 2024 baseline that proved the idea — 260K params on an ESP32-S3.
  • Pete Warden — petewarden.com2026-08TinyML's founding voice — TensorFlow Lite Micro, the TinyML book, Useful Sensors.
  • Daniel Situnayake — situnayake.com2026-08Co-author of the TinyML and AI at the Edge books that taught the field.
  • Max Braun — llama4micro2026-08Llama inference on a $40 Coral Micro board — an early proof the small end was reachable.
  • Simone Salerno — eloquentarduino.com2026-08The EloquentArduino libraries — ML on Arduino for people without a PhD.
  • Tao Wei, Ken Qing Yang & Alfred Xu — FastFlowLM2026-08The academics who lit up AMD's dark NPUs — an Ollama-like LLM runtime AMD acquired in July 2026.
  • Shawn Hymel — shawnhymel.com2026-08Embedded-ML educator whose courses onboarded a generation of edge developers.

The reading room

The publications we read to write Edge — from the US, India, and Europe.

Independent publications listed with appreciation — Edge has no affiliation with any of them, and inclusion implies no endorsement in either direction.

Subscribe to the Edge dispatch

Microcontroller-AI news + bench logs — no spam, one-click unsubscribe.